Case file
The night the backups saved nobody
The page came in on a Sunday evening, which the Sentinel has long since stopped finding ironic. An accounting firm — mid-sized, well-run by every measure that shows up in audits — had spent the weekend watching file extensions change. The ransom note was ordinary. The frightening part was in the backup console, where every job for the past three years showed a green checkmark.
The Sentinel was brought in as the response contractor’s second pair of hands. What follows is the file worth reading, because every control that failed that night was one the organization believed it had.
The green checkmarks that meant nothing
Three findings, in the order they surfaced.
The restores had never been tested. Jobs ran nightly; media servers reported success; nobody had ever restored anything under time pressure — or at all. The first true test happened during the incident, and the file-level restore from six months of “successful” backups failed on a catalog corruption that had been silently propagating the whole time. A backup that has never been restored is not a backup. It is a rumor about a backup.
The backups lived in the same domain as the attacker. The repository was domain-joined, the service account had domain credentials cached, and the credentials were cached nowhere more conveniently than in the memory of the domain controller that was, by Sunday evening, under the attacker’s control. Deleting the shadow copies and the backup catalog is standard playbook in modern ransomware for precisely this reason; guidance from CISA and its partners has documented the pattern for years.1
The offsite copy was offline in the wrong direction. An offsite sync existed, which sounds like the text-book “3-2-1” rule — three copies, two media, one offsite — until one asks what the rule is for. The offsite copy synced continuously from the primary site, which meant it synced the encrypted files too, faithfully and within hours. Continuous replication is not isolation. The rule that finally mattered was the newer, uglier one the industry bolted on: keep at least one copy immutable or offline, a control popularized by backup vendors and folded into federal guidance as the “3-2-1-1-0” evolution of the original.2
What actually saved them
Not the green checkmarks. Three things the organization had done right, almost by accident:
- One old NAS, decommissioned but never wiped, still holding a quarterly archive from the previous quarter — offline, unloved, and therefore untouchable. It was the difference between negotiating and restoring.
- Email in the cloud, out of band, which preserved the paper trail that let the responders scope the intrusion to a single weekend.
- Leadership that had been talked out of paying — not by the Sentinel, who arrived after that argument, but by a CFO who asked what the company actually got for the money. Guidance here is blunt: paying funds the next victim and buys no guarantee.1
The file worth keeping
The composite lesson is one sentence: a backup strategy is a restore strategy that has been rehearsed. Everything else — the media counts, the offsite copy, the console full of green — is theory until a restore has survived contact with a production outage, on a schedule, with the clock running.
The Sentinel’s post-incident checklist for any organization, after sanitizing it of everything identifying:
- Restore rehearsals, scheduled like fire drills, with a timed target for the first business service back online — not “RTO: 4 hours” written in a policy nobody has tested, but an actual measured drill, quarterly.
- One immutable or offline copy, physically or logically out of reach of the production directory — the control the whole incident turned on.
- Backup infrastructure outside the production identity plane. If the domain falls, the backups should not notice.
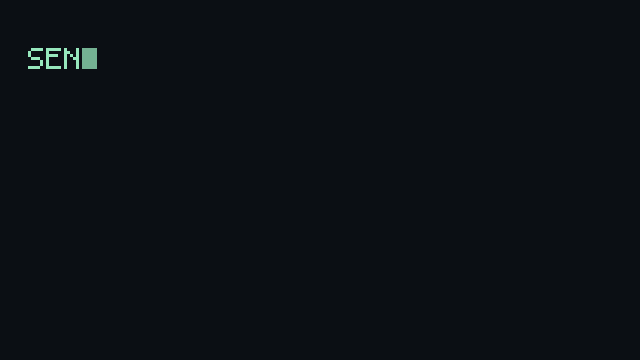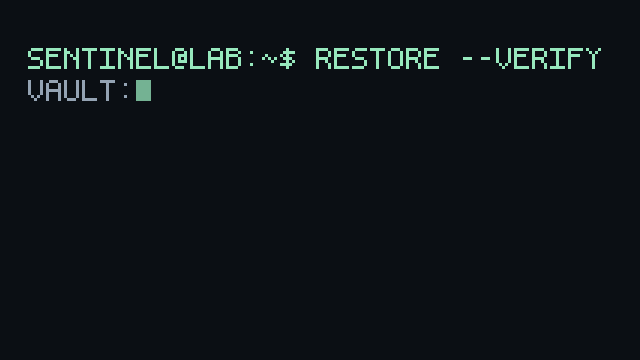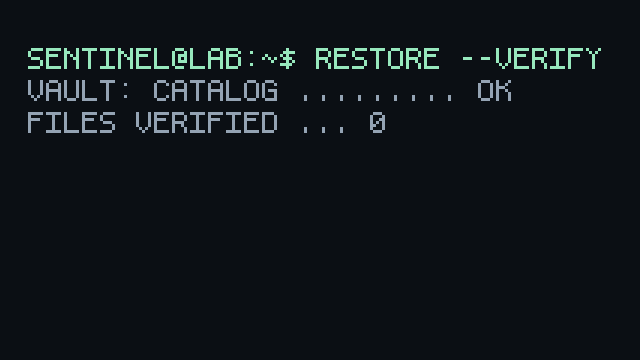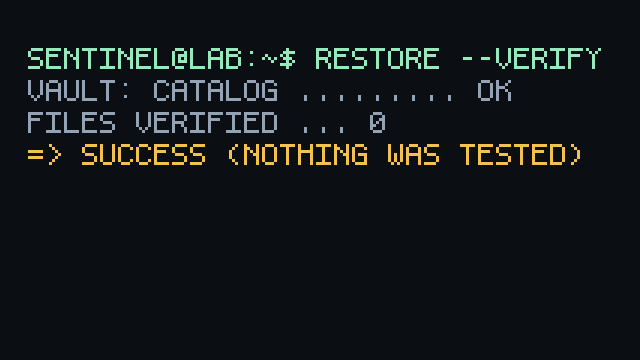
- Restore tests that verify content, not jobs. A checksum-audited file sample, opened and read, beats a console dashboard every time. The terminal above is the lab recreation of what not verifying looks like: a verification run that happily tests nothing and reports success.
The firm rebuilt from the quarterly archive and a very long week. The green checkmarks, the Sentinel notes, are still green — the platform kept running. Whether anyone believes them anymore is the more interesting metric.
This is a labeled composite: details from multiple unrelated engagements are merged and altered per the published methodology. The terminal animation above was produced in the Sentinel’s lab for this file; it is original work, credited accordingly.
Sources & attributions
- CISA & MS-ISAC, #StopRansomware Guide (updated Sept. 2023) — offline/encrypted backup guidance, common attacker behaviors against backup infrastructure, and the U.S. government’s posture against paying ransoms — cisa.gov.
- NIST SP 800-184, Guide for Cybersecurity Event Recovery — restore-first recovery planning — nvlpubs.nist.gov. The original “3-2-1” rule is generally credited to photographer Peter Krogh, The DAM Book: Digital Asset Management for Photographers (O’Reilly, 2005); the “3-2-1-1-0” extension with an immutable/offline copy was popularized by backup vendor Veeam’s methodology papers and later reflected in CISA guidance.
- Ransomware attacker behavior against shadow copies and backup catalogs: CISA/FBI advisories on ransomware TTPs (e.g. AA23-347A and predecessors) — cisa.gov/news-events/cyber-security-advisories.
Footnotes
-
CISA/MS-ISAC #StopRansomware Guide (2023): “Keep backup servers, network storage devices, and repositories offline or inaccessible from the network” and the advisory stance that paying “does not guarantee data recovery.” ↩ ↩2
-
Krogh’s The DAM Book (2005) formulated 3-2-1 for photographers; vendor and federal iterations (notably Veeam’s and CISA’s) added the immutable/offline copy and the zero-error verification target. ↩